AI Agents Are Joining Your Microsoft 365 Tenant. Is Your Security Model Ready?
Identity, permissions, data and governance checks before agents enter production
Technical blog post | Microsoft 365 | Microsoft Entra | Copilot Studio
AI agents are starting to appear everywhere in the Microsoft ecosystem.
Microsoft 365 Copilot. Copilot Studio. SharePoint. Teams. Azure. Microsoft Foundry. Third-party platforms. Custom applications.
And we’re quickly moving past agents that simply answer questions.
We now have agents that can search organisational data, interact with APIs, call tools, respond to events and perform work on behalf of users.
That changes the conversation for IT.
If someone comes to me and says, “We’ve built an AI agent that can read support tickets, check Microsoft 365, update the ticket and perform some remediation“, my first question isn’t which model they’re using.
I want to know: Who is this agent? Then: What can it see, and what can it do?
Those questions sound simple, but once an agent can interact with Microsoft 365 data and production systems, they become security architecture questions.
I don’t think the answer is to block agents. They’re going to become part of normal enterprise IT.
But I also don’t think we should repeat what happened with service accounts, enterprise applications and Power Platform, where organisations sometimes discovered years later that they had hundreds of identities, applications and integrations that nobody really owned anymore.
We have an opportunity to get ahead of that with agents. So if I were preparing a Microsoft 365 environment for agents today, this is where I would start.
First, understand that an agent needs an identity
For years, Microsoft Entra ID has primarily dealt with two broad identity types that most administrators understand well. We have human identities, and we have workload identities such as applications and service principals.
AI agents introduce another requirement. An agent might operate interactively on behalf of a user. Another might run autonomously in the background. Another might need its own persistent access to resources. At scale, an organisation could have hundreds or thousands of these identities.
Microsoft has introduced Microsoft Entra Agent ID specifically to address this problem. Agent ID extends the Microsoft Entra identity and governance model to AI agents. It introduces agent-specific identity constructs, lifecycle relationships and security capabilities so agents don’t simply disappear into the same application estate we’ve been trying to clean up for years.
This is already showing up in Copilot Studio. New Copilot Studio agents automatically receive an Entra Agent ID. Microsoft currently implements these Copilot Studio Agent IDs as service principals with an Agent subtype, while older Copilot Studio agents created before Agent ID was introduced can still use traditional app registrations.
That distinction matters. If I create a new agent in Copilot Studio today, I can open Settings, Advanced, Metadata and find the Entra Agent ID associated with it.
I can then take that identity into Microsoft Entra and start treating the agent like something that needs to be governed.
That is exactly what I want. An AI agent shouldn’t just be a thing somebody built in a portal. It should have an identity I can discover, investigate and eventually retire.
Agent ID is more than renaming a service principal
This is where the architecture becomes interesting. Microsoft isn’t simply putting a different label on application identities.
The broader Entra Agent ID platform introduces concepts specifically designed around agents. One of those is the agent identity blueprint.
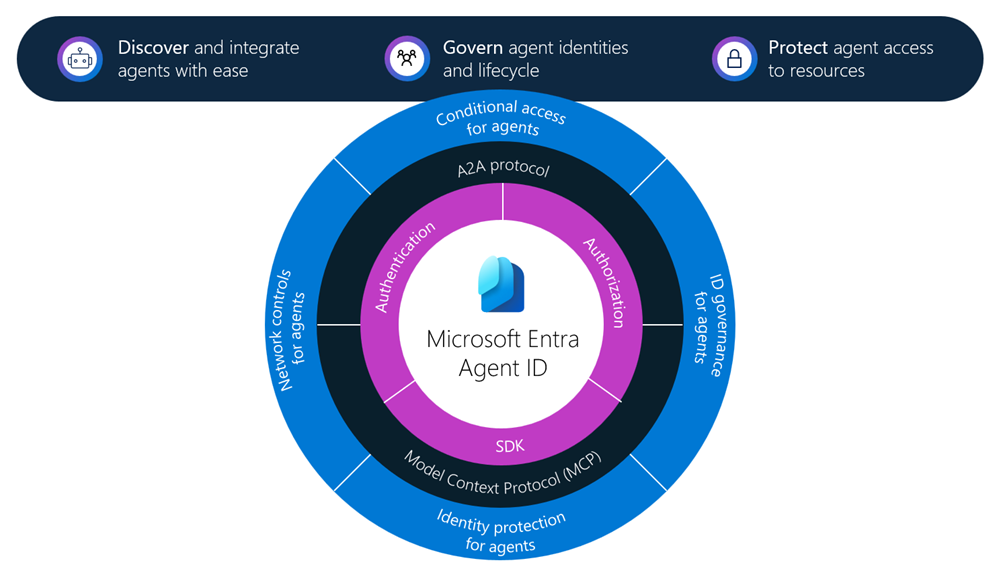
A blueprint acts as the authentication and policy foundation for one or more agent identities. The blueprint holds credentials and can be used to establish common security configuration across the agents created from it.
The individual agent identities themselves don’t carry their own credentials in the same way a traditional service principal might. They can authenticate using tokens obtained through their blueprint.
That parent and child relationship matters when we start thinking about scale. Instead of treating every agent as an unrelated application, we can build identity architecture around groups of agents with common security requirements.
Microsoft has also introduced concepts such as sponsors. A sponsor provides business accountability for an agent without necessarily giving that person technical control over the identity.
I really like that distinction. We have struggled with this exact problem with applications for years.
The application owner is often either a highly privileged administrator who doesn’t actually own the business process, or somebody from the business who was made an application owner even though they shouldn’t be managing credentials and permissions.
Agents give us an opportunity to separate those responsibilities properly. Someone can be accountable for why the agent exists without automatically receiving technical control over its identity.
Before securing agents, find out how many you have
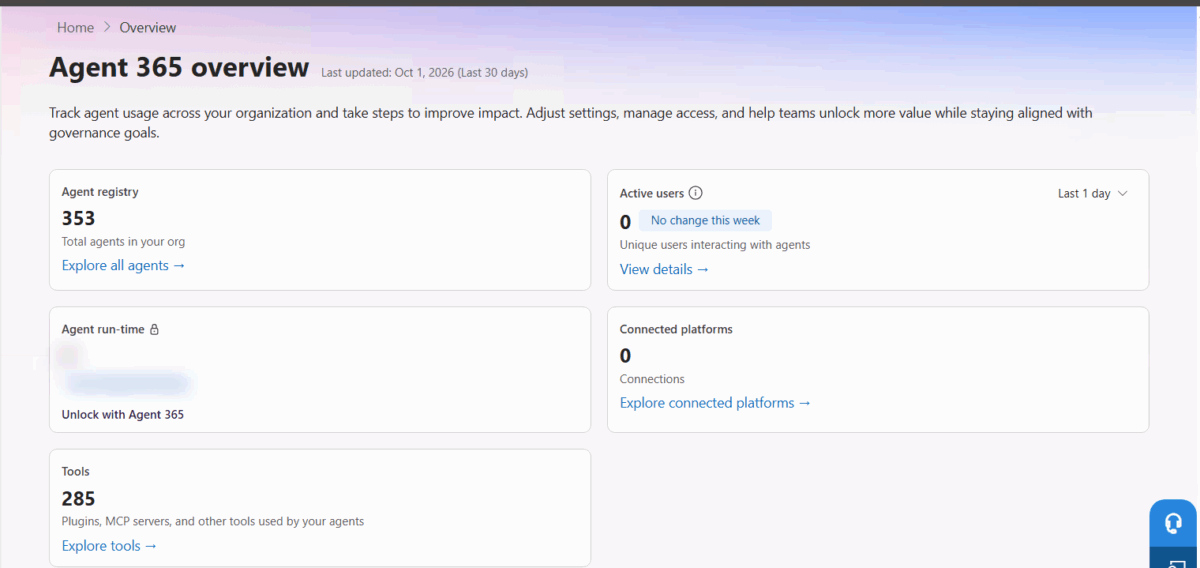
This would be my first practical exercise with an organisation. Show me the agents. Not the PowerPoint slide describing the AI strategy. I want the inventory.
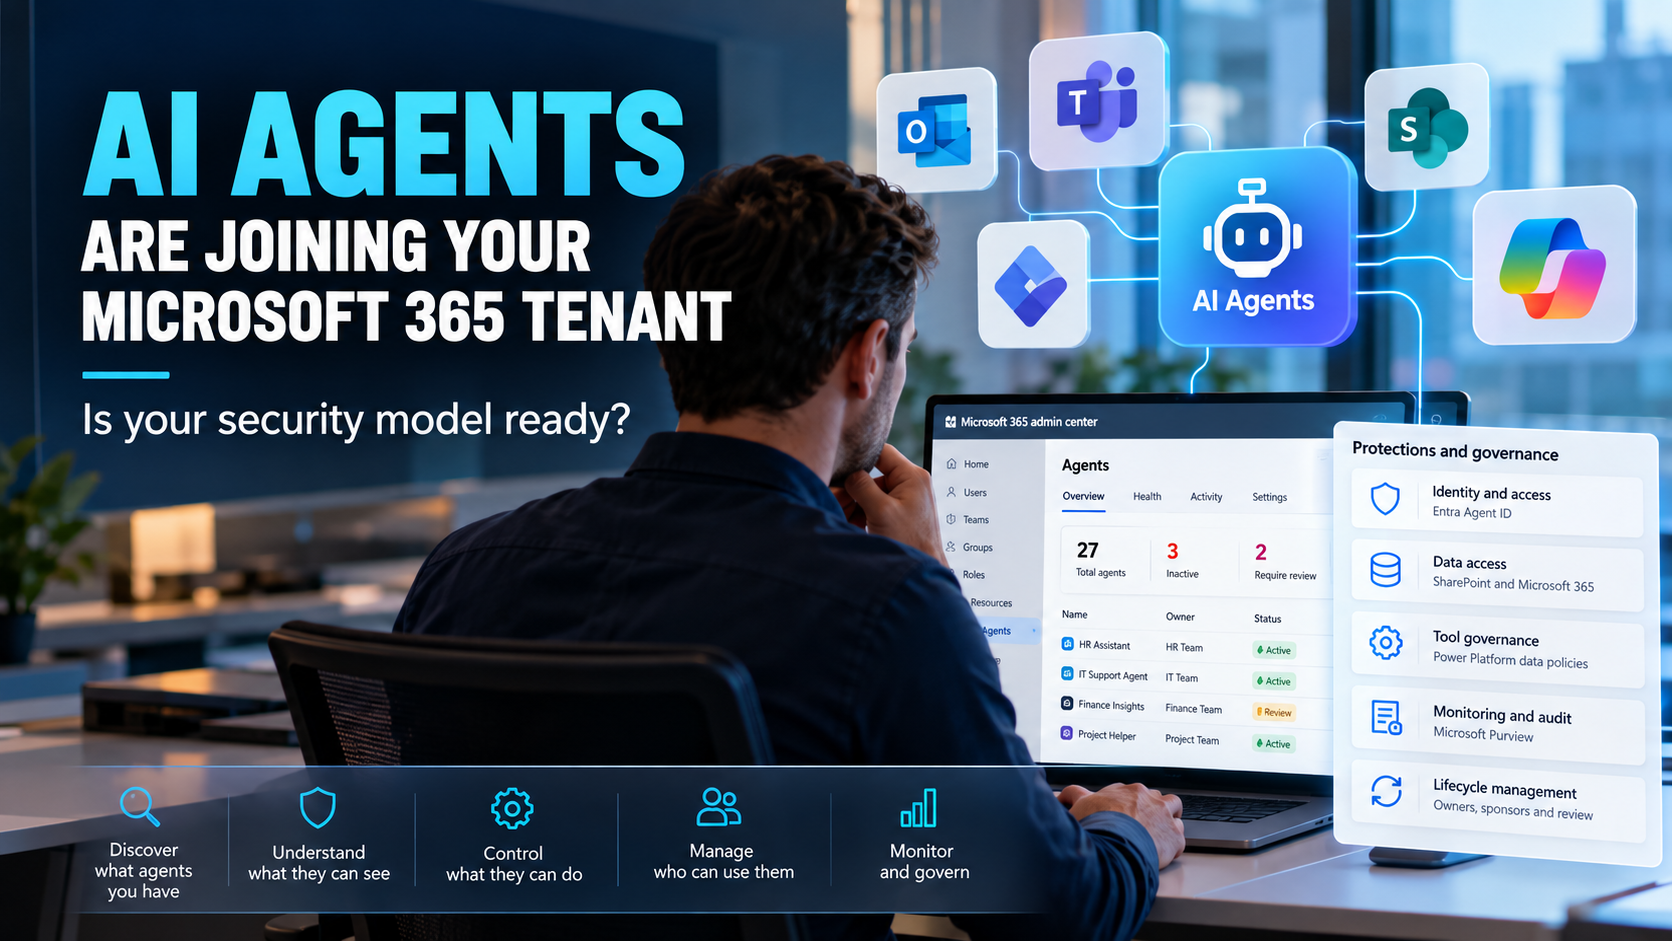
Microsoft now exposes agent management through the Microsoft 365 admin center, where administrators can review agents and govern how they’re accessed, published and deployed.
That inventory is going to become increasingly important. Today you might have five agents. Six months from now you might have fifty.
A year from now, you might discover that HR built twelve, Finance built eight, the service desk has fifteen, developers created another twenty, and somebody installed a third-party agent nobody in security knew about.
The problem isn’t necessarily that those agents are malicious. The problem is that we have lost visibility.
Before I approve an enterprise agent strategy, I want to know who created each agent, who is responsible for it, where it is published, who can use it, what knowledge it can access, which tools it can call, whether it performs autonomous actions, when it was last used and whether it still needs to exist.
That isn’t AI governance theatre. That’s basic asset management.
The next question is whose permissions the agent is actually using
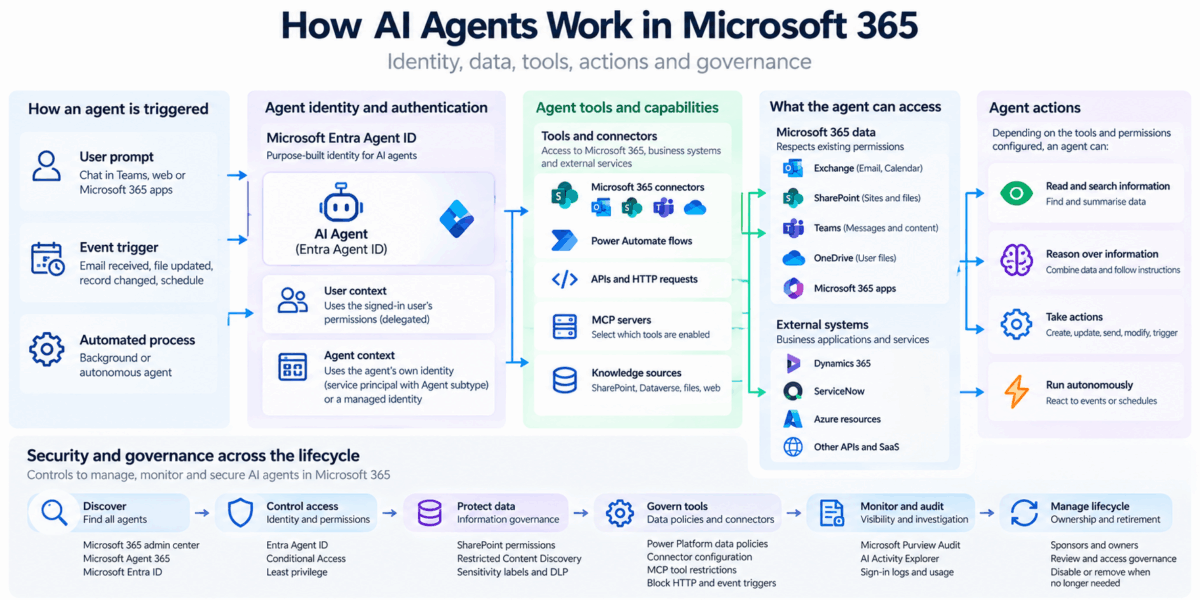
This is probably one of the most important things to understand when building agents. An agent doesn’t automatically have one universal permission model.
The way it accesses a system depends on how the agent and its tools have been configured. Copilot Studio provides a good example.
A tool can use user authentication, where the user interacting with the agent authenticates to the connected service. Or the tool can use agent author authentication, where credentials supplied by the agent maker are used.
Those are very different security models.
Imagine I’ve built an HR agent. Shaun asks: Show me my remaining annual leave.
If the tool uses Shaun’s identity to access the HR system, the backend sees Shaun and should return only information Shaun is authorised to access. That makes sense.
Now imagine the same agent is using the agent author’s connection to the HR system. The agent might now be accessing that system with the permissions of the person who built it.
If that account can see every employee’s HR record, we have changed the security boundary considerably.
The agent itself hasn’t somehow hacked the HR system. We gave it a more privileged connection.
Microsoft explicitly recommends user authentication where access needs to be restricted according to the individual user’s permissions.
There are legitimate reasons to use author-provided credentials, particularly for autonomous processes and low-risk shared services. But it needs to be a deliberate architecture decision. It shouldn’t happen because somebody clicked through the agent wizard until it worked.
Maker credentials deserve serious attention
Microsoft has introduced administrative controls specifically for this problem. In Power Platform, administrators can control whether makers are allowed to use their own credentials for agent tools or whether tools must use end-user credentials.
This matters because maker-provided credentials can create a privilege path. If an agent uses my connection to perform an action, somebody interacting with that agent might be able to cause an operation to run using permissions that belong to me rather than them.
There is an important trade-off, though. If you completely disable maker-provided credentials and force end-user authentication everywhere, autonomous agents that need to run without a live user can stop working because there is nobody present to authenticate the tool call.
So the answer isn’t to ban maker credentials everywhere. The answer is to decide where they’re appropriate.
A user-facing HR agent probably shouldn’t quietly inherit the HR manager’s access. A scheduled integration agent that needs to update a backend system might legitimately require a non-user identity or controlled connection.
Those are different workloads and should be designed differently.
Your biggest AI problem might already exist in SharePoint
This is the area I would investigate before rolling out Microsoft 365 agents broadly: SharePoint permissions.
Microsoft 365 Copilot and Microsoft 365 agent experiences generally respect the permissions that already exist. That sounds reassuring. And it is.
But it also means that if your permissions are a mess, AI doesn’t magically fix them.
Imagine Finance has a SharePoint site containing salary spreadsheets. Someone accidentally granted a broad group access two years ago. Nobody noticed because most employees didn’t know the site existed.
Technically, the permissions were already wrong. Now introduce an AI experience that can search and reason across organisational information.
The AI hasn’t created the access. The user already had it. What has changed is discoverability.
Information that was previously buried three folders deep on a SharePoint site can become considerably easier to surface.
That is why I think AI readiness and SharePoint governance are really the same conversation. Before worrying about prompt engineering, I want to know whether your Microsoft 365 permissions actually represent who should have access to the information.
Restricted Content Discovery can buy you some breathing room
Microsoft has introduced Restricted Content Discovery in SharePoint for exactly this kind of governance scenario.
If I identify a sensitive site that needs a permissions review, I can temporarily restrict its content from organisation-wide discovery experiences and Microsoft Copilot responses while the site is being reviewed.
The important word there is temporarily.
Restricted Content Discovery does not change the underlying SharePoint permissions. If Shaun already has permission to the Finance site, enabling Restricted Content Discovery doesn’t suddenly revoke Shaun’s access.
It changes discoverability, not authorisation. That makes it useful while we clean up oversharing, but it is not a replacement for fixing the permissions.
You can currently configure it from SharePoint admin center, Active sites, select the site, Settings, Restrict content from Microsoft Copilot.
Microsoft supports the control across up to 20,000 SharePoint sites, but recommends using it selectively because restricting large amounts of content can reduce the completeness of search and Copilot responses.
There is also an important change administrators need to know about. Restricted SharePoint Search is being retired. As of 31 July 2026, Microsoft blocks new enablement and directs organisations toward controls such as Restricted Content Discovery, SharePoint Advanced Management and Microsoft Purview.
So I wouldn’t start a new Copilot governance project around Restricted SharePoint Search now. I would build around the controls Microsoft is actively taking forward.
Reading data is one thing. Acting on it is another.
This is where I think agent security becomes considerably more interesting.
There is a massive difference between an agent that can tell me whether a user has an active AVD session and one that can log the user off.
The first is retrieving information. The second changes production state.
Now extend that idea. An agent might be able to read email. Another can send email. One can check group membership. Another can modify the group. One can investigate an Azure VM. Another can restart it. One can retrieve an incident. Another can close it.
Once an agent can take actions, I want to understand its blast radius.
I find it useful to think about an agent in three stages: READ, REASON, ACT.
READ: What information can the agent retrieve?
REASON: What instructions, data and external content can influence the agent’s decision?
ACT: Which tools, connectors, APIs and systems can the agent change?
The further we move toward ACT, the more interested I become in permissions, approvals, auditability and rollback.
This is particularly important for autonomous agents because a human might not be sitting there approving every individual operation.
Tools are where an agent becomes powerful
An LLM by itself isn’t going to reset your user account. The interesting part is what we connect to it.
Copilot Studio agents can use connectors, APIs, Power Automate flows, knowledge sources and MCP servers. Each tool expands what the agent can interact with.
That means tool governance is just as important as model governance.
If I give an agent an MCP server exposing twenty tools and the agent only needs three, why are all twenty enabled?
Copilot Studio allows individual MCP tools to be disabled. When Allow all is disabled, you can explicitly select which tools the agent is allowed to use. New tools added to that MCP server are then disabled by default.
That’s exactly the behaviour I want. Give the agent what it needs, not everything the server happens to expose.
This is simply least privilege applied to agent tooling.
Data policies become part of your AI security boundary
Power Platform data policies are going to be extremely important for organisations building Copilot Studio agents.
These policies allow administrators to control how agents interact with data sources and services.
Connectors can be classified into Business, Non-business and Blocked groups.
That matters because you might be perfectly happy for an agent to move information between SharePoint and Dataverse while being completely unhappy about that same agent sending organisational data to an unmanaged external service.
Microsoft also provides agent-specific controls through data policies. Administrators can block HTTP requests, particular knowledge sources, Power Platform connectors used as tools, skills, publication channels and event triggers.
Data policy enforcement applies across Copilot Studio tenants, and Microsoft removed the old exemption model.
This is where I would spend quite a bit of time before opening Copilot Studio broadly to citizen developers.
What are makers allowed to connect to? Where can agents be published? Can they call arbitrary HTTP endpoints? Can they use public websites as knowledge? Can they use event triggers? Can they publish anonymously?
Those are administrative decisions, not decisions I want every individual maker making independently.
Anonymous agents need to be intentional
Copilot Studio agents use Microsoft authentication by default, but makers can configure agents for scenarios where no authentication is required unless administrative controls prevent it.
There are valid use cases for public agents. A public website support bot doesn’t necessarily need every visitor to authenticate.
But an internal agent with access to organisational tools or sensitive information is a very different thing.
Microsoft’s Copilot Studio security scan warns makers when they change an agent from secure defaults, including configuring no authentication, using maker-provided credentials or sharing the agent with the entire organisation.
For enterprise environments, I would decide at the platform level whether makers should even be allowed to publish unauthenticated agents.
That is another area where Power Platform data policies and administrative authentication controls matter. The secure default should not depend on every maker remembering the security architecture.
Event triggers change the threat model again
A normal conversational agent waits for someone to ask it something. An autonomous agent might not.
It can react to an event. An email arrives. A record changes. A ticket is created. A scheduled process runs. Something happens in another system.
The agent responds without somebody explicitly sitting in front of Teams typing a prompt.
That is incredibly useful. It also changes the risk.
The question is no longer only: What can a user convince the agent to do? It becomes: What events can cause the agent to act?
Microsoft allows administrators to block event triggers through Copilot Studio data policies. Microsoft specifically calls out data exfiltration, unwanted execution and consumption as reasons an organisation might restrict them.
I wouldn’t automatically disable autonomous triggers. That defeats a large part of the value of agents. But I absolutely want to know which production agents use them.
An autonomous agent deserves a higher level of review than a simple knowledge agent answering questions from approved SharePoint content.
MCP needs governance too
Model Context Protocol is becoming an important way of connecting agents to tools and external systems.
From an architecture perspective, I like it. It gives us a standard way for agents to discover and use capabilities exposed by external services.
From a security perspective, I still ask the same old questions. Who operates the MCP server? How does the agent authenticate? What tools does it expose? What data can those tools return? Which actions can they perform? Can the tool definitions change? What happens when a new tool is added?
In Copilot Studio, MCP server access relies on Power Platform connectors, which means the existing Power Platform data policy model remains relevant.
That is good. New technology shouldn’t mean throwing away the governance controls we already have.
Agents need owners, but they also need lifecycle management
Imagine somebody in Finance creates Invoice Reconciliation Agent. It works brilliantly. A year later, the employee who built it leaves.
What happens to the agent? Who owns the business process now? Who understands its connections? Who reviews its permissions? Who knows whether it is still being used? Who retires it when the finance platform is replaced?
Applications don’t resign. Neither do agents.
Microsoft Entra Agent ID is introducing lifecycle concepts specifically because this becomes a serious problem at scale.
Sponsors provide business accountability. Owners can provide technical administration. Identity Governance capabilities can then be used to manage the lifecycle and access around agents.
This is the same lesson we’ve already learned from service principals. An identity without an owner eventually becomes an identity nobody wants to touch because nobody knows what will break.
I don’t want us repeating that with agents.
Monitoring an agent means more than knowing whether it ran
If an agent makes a mistake or becomes involved in a security incident, I need evidence.
I want to know who invoked it, what they asked, what information the agent used, which files were referenced, which tool was called, what action happened and what identity performed that action.
Microsoft is building this visibility across Entra, Microsoft 365 and Purview.
Entra provides authentication and identity visibility for Agent IDs. Microsoft Purview provides auditing around Copilot and agent interactions.
For deeper AI data-security investigation, Data Security Posture Management for AI and Activity Explorer can provide visibility into prompts, responses, web grounding queries and referenced files, subject to the relevant licensing and capabilities.
That becomes extremely valuable during an investigation.
Imagine a user reports: The agent showed me a confidential document I don’t think I should have seen.
I don’t want to guess what happened. I want to establish what the user asked, which resource was referenced, why the user had access to it and whether the underlying SharePoint permissions were correct.
That is the difference between AI monitoring and simply collecting usage statistics.
Agent sprawl is probably coming
This is the operational problem I think IT departments should start planning for now.
Agents are becoming easier to create. That’s a good thing. It means teams can automate processes without waiting six months for a traditional application-development project.
But easier creation also means more creation. We’ve already seen this with Power Platform. Successful low-code platforms don’t produce five applications. They produce hundreds. Agents are likely to follow the same path.
Imagine opening the Microsoft 365 admin center two years from now and seeing 327 agents. Some are business critical. Some are experiments. Some haven’t been used for nine months. Some access sensitive SharePoint sites. Some call external APIs. Some use autonomous triggers. Some have owners who left the company. And four of them nobody can explain.
That isn’t really an AI problem. It’s an IT governance problem.
The organisations that handle agents well won’t necessarily be the ones with the most restrictive AI policies. They’ll be the organisations that know what agents they have, who owns them, what they can access and when they should be retired.
My five questions before an agent goes into production
Who is it?
What identity represents the agent? Does it have an Entra Agent ID? Who owns it? Who sponsors it? How does it authenticate?
What can it see?
Which Microsoft 365 data can it discover? Which SharePoint sites? Which knowledge sources? Which external systems? Is the underlying access actually appropriate?
What can it do?
Can it only retrieve information? Can it send email? Can it update records? Can it modify identities? Can it change infrastructure? Which tools and APIs make those actions possible?
Who can use it?
Is it available to one team, the entire organisation, external users or anonymous users? Does the agent act using the end user’s permissions or a shared privileged connection?
Can we govern it?
Can we find it? Can we audit it? Can we determine what it did? Can we disable it quickly? Can we remove its access? And when the agent is no longer needed, do we have a process to retire it?
If I can’t answer those five questions, I’m not comfortable calling the agent production ready.
The AI doesn’t make your existing security problems disappear
This is probably the biggest point I want people to take away from this.
Agents don’t replace identity governance. They make it more important.
They don’t replace SharePoint permissions. They make oversharing more visible.
They don’t replace least privilege. They make excessive tool permissions more dangerous.
They don’t replace data governance. They make it easier to move and reason over information at scale.
And they don’t replace monitoring. Once an agent can act autonomously, monitoring becomes even more important.
The biggest mistake we could make is treating AI agents as a completely separate security programme. They’re not.
They sit on top of the identity, permissions, applications, APIs, connectors and data that we already manage.
If those foundations are weak, giving an agent access to them doesn’t strengthen anything. It simply gives us a faster way to interact with the weakness.
Final thoughts
I’m genuinely excited about where agents are going.
An agent that can investigate an incident, gather evidence, correlate information and present an engineer with the likely root cause can save an enormous amount of time.
An agent that can take an approved remediation action after that investigation is even more useful.
But there is a line between useful automation and uncontrolled privilege. That line is identity and governance.
Before I care about how intelligent an agent is, I want to know who it is.
Before I care how many tools it has, I want to know why it needs them.
Before I allow it to act autonomously, I want to understand its blast radius.
And before we deploy hundreds of agents across Microsoft 365, I want to know how we’re going to find, monitor and eventually retire them.
AI agents are going to become another identity population that IT has to manage. We should treat them that way from the beginning.
Before your next agent goes into production, ask five questions: Who is it? What can it see? What can it do? Who can use it? Can we govern it?
If you can’t answer those clearly, the agent probably isn’t ready for production yet.
Microsoft references
- Microsoft Entra Agent ID overview
- Copilot Studio agent identities
- Configure end-user authentication in Copilot Studio
- Copilot Studio data policy examples and controls
- Restricted Content Discovery in SharePoint
- Restricted SharePoint Search
- Microsoft 365 Copilot security and governance controls
- Manage Copilot agents in the Microsoft 365 admin center